The network continues to be the bottleneck for large-scale AI workloads, and trillion-parameter models are pushing traditional infrastructure past its breaking point.
On 3 June 2025, Broadcom (NASDAQ:AVGO) announced that it was shipping Tomahawk 6 for scale-up and scale-out AI networks. Its TH6-Davisson announcement followed on 8 October 2025, ahead of OCP 2025, held from 13 to 16 October 2025.
At a Glance
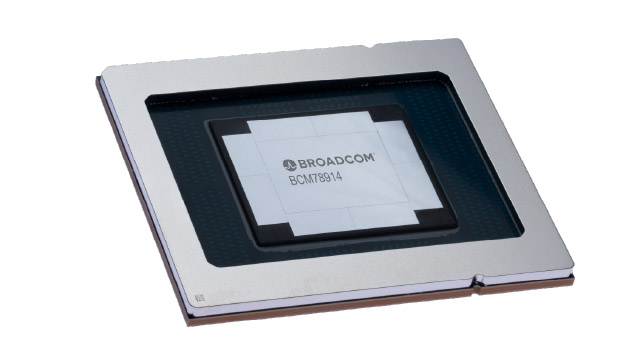
Tomahawk 6 switch silicon delivers a staggering 102.4 Tbps of throughput with up to 512 ports of 200GbE, 256 ports of 400GbE or 128 ports of 800GbE. That is double the throughput of its Tomahawk 5 predecessor, which debuted in 2022. The architecture supports up to 64 ports of 1.6TbE. Its 512 SerDes lanes run at 200G PAM4, and an option offers 1,024 lanes at 100G PAM4 instead. Built on 3nm process technology, it has what Broadcom calls the world's highest radix of 200GbE ports, along with industry-leading SerDes and enhanced power efficiency for AI/ML workloads.
Broadcom's Tomahawk silicon has been the familiar merchant silicon sitting inside networking switch gear of many industry-leading vendors for more than a decade now. Over the past several years, Broadcom has been focusing on accelerating AI workloads, which is the stated goal of the TH6 silicon as well. What's different, however, is the overwhelming scale of AI workloads, which is what Broadcom aims to address with the new silicon.
Credit: Broadcom
Scale-Up and Scale-Out Architecture
One of the biggest technical achievements of the TH6 is its ability to support both scale-up and scale-out networking requirements within the Ethernet network.
The new silicon supports scale-up clusters with up to 512 XPUs and scale-out networks with over 1 million XPUs. The 512-port density per chip is critical here. It enables you to build flat, low-latency clusters without the complex multi-tier spine-leaf architectures that add hops and microseconds. For scale-up AI training clusters, you can connect 512 accelerators with a single switch tier.
For massive scale-out deployments, TH6 lets you build 100,000+ XPU networks with just two tiers at 200 Gbps per link. Traditional data center switches would require three or four tiers to reach this scale, and each additional tier adds latency and potential congestion points.
The chip also supports arbitrary topologies, including scale-up, Clos, rail-optimized, rail-only, and torus configurations. This flexibility means you can optimize for your specific workload characteristics rather than being locked into a single architecture.
Ultra-low Latency Packet Buffering
AI training workloads generate massive all-to-all communication patterns, such as all-reduce and all-gather collective operations. When thousands of GPUs or XPUs (TPUs, NPUs, or other AI accelerators) try to send data simultaneously, packet buffering becomes the bottleneck.
TH6 features the industry's most advanced 102.4 Tbps packet buffer architecture. This isn't just about total buffer size. It's about buffer throughput and how quickly the switch can absorb microburst traffic without dropping packets or creating tail latency.
The architecture is specifically optimized for RoCEv2 and other RDMA protocols that AI frameworks depend on. RDMA is extremely sensitive to packet loss and reordering. Even a single dropped packet can stall an entire training job for milliseconds while the transport layer recovers.
By maintaining line-rate performance even under heavy congestion, TH6 keeps expensive GPU clusters productive instead of idle waiting for network recovery.
Advanced Congestion Management
AI workloads create low-entropy flows. Unlike web traffic or database queries with thousands of independent connections, AI training generates synchronized, elephant flows where many nodes send similar data patterns at exactly the same time.
Traditional load balancing fails here because standard ECMP hashing can't effectively distribute these synchronized flows. Some paths end up overloaded while others sit idle.
TH6 includes hardware-based adaptive routing and dynamic load balancing designed specifically for these AI traffic patterns. Its Cognitive Routing 2.0 features include advanced telemetry, dynamic congestion control, rapid failure detection and packet trimming. The chip monitors congestion in real-time and steers flows away from hot spots automatically, maximizing network utilization.
It also supports end-to-end congestion control and hardware-based link failover. Broadcom describes TH6 as compliant with Ultra Ethernet Consortium specifications. When a link fails, the switch reroutes traffic in hardware without waiting for control plane convergence. This keeps training jobs running and reduces job completion time, which directly translates to lower costs per training run.
Tomahawk 6 Davisson Co-Packaged Optics Announcement
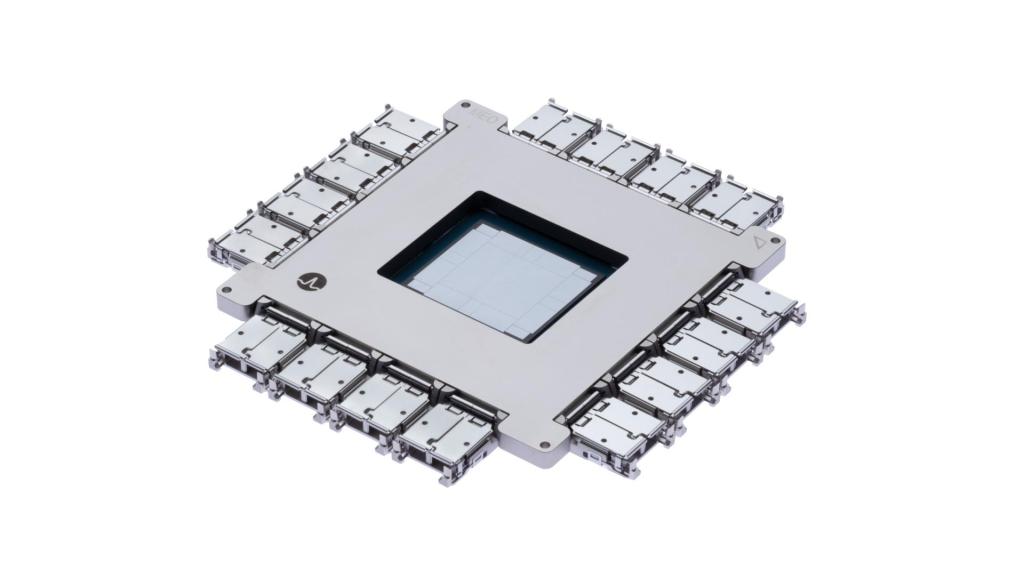
On 8 October 2025, Broadcom announced that TH6-Davisson, its third-generation CPO solution, was shipping. At launch, the company was sampling it to early access customers and partners. The BCM78919 combines 16 optical engines rated at 6.4 Tbps each and supports field-replaceable laser modules.
Traditional pluggable optics are hitting their limits at 102.4 Tbps speeds. They consume excessive power, introduce latency, and require larger system footprints. TH6-Davisson addresses these issues by directly integrating optical engines onto the same package as the Ethernet switch using TSMC COUPE (NYSE:TSM) technology. By shortening electrical paths and eliminating the need for additional DSPs and retimers, CPO significantly reduces power while enabling higher bandwidth density at the chip edge.
The result is a 70% reduction in optical interconnect power consumption compared to traditional pluggable solutions. For hyperscalers running massive AI clusters, this translates to millions of dollars in reduced energy costs.
Link stability is equally critical. Even minor link flaps can cause measurable drops in GPU utilization during training runs. Broadcom says the integrated CPO design improves link stability and cluster reliability by eliminating many sources of manufacturing and test variability inherent in pluggable transceivers.
TH6-Davisson operates at 200 Gbps per channel and is designed to interoperate with DR-based transceivers, LPO and CPO optical interconnects running at 200 Gbps per channel.
Credit: Broadcom
The Bottom Line
Tomahawk 6 addresses the network bottlenecks constraining AI infrastructure at scale. By maintaining line-rate performance during congestion bursts and providing unified Ethernet for both scale-up and scale-out, it keeps GPU clusters productive and reduces job completion times.
On 3 June 2025, Broadcom said Tomahawk 6 was shipping as the world's first 102.4 Tbps Ethernet switch chip. On 8 October 2025, it announced TH6-Davisson as the first 102.4 Tbps Ethernet switch with co-packaged optics.
Alex Cronin
Alex Cronin is the founder of Hardware Nation and Nanites AI. He is a graduate of Georgia Tech with 20 years of experience in networking and data center infrastructure across enterprises, service providers and hyperscalers. His work spans traditional and open networking, production SONiC deployments, multivendor integration and direct collaboration with manufacturers and engineering teams. Hardware Nation has served organizations including NASA, Lockheed Martin, Accenture, Stanford University and Georgia Tech.
Alex leads engineering teams and contributes directly to architecture, code, integration and evaluation. At Nanites AI, he has led nearly two years of development of an agentic NetOps platform for network troubleshooting. He also develops AI automation for product research and leads business operations at Hardware Nation.
Nanites AI has been cited in Gartner’s Market Guide for Agentic NetOps Software, covered by InformationWeek and discussed by Cisco DevNet. It was selected as one of 12 finalists from more than 400 applicants in the 2025 T Challenge, organized by T-Mobile and Deutsche Telekom. Alex has presented his work at Deutsche Telekom in Bonn, CableLabs and Network X Americas.